LLM Fine-Tuning

Models tuned to your domain, your voice, your tasks

When prompting and retrieval hit their limits, fine-tuning teaches a model your specific patterns, lifting accuracy and consistency, cutting cost, and capturing a voice and behavior generic models can't. We do it with the evaluation rigor it demands.

OverviewAI · LLM Fine-Tuning

Fine-tuning is powerful, and the wrong first move more often than not

Fine-tuning has an allure: a model trained on your data, behaving exactly as you want. Sometimes that's exactly right. Often it isn't: prompting or retrieval would solve the problem faster, cheaper, and with less maintenance, and fine-tuning would be expensive effort aimed at the wrong target. The first job of a good fine-tuning partner is honesty about whether you need it at all. When you genuinely do, the second job is doing it with the data quality and evaluation rigor that separate a model that's better from one that's quietly worse.

Villaex fine-tunes when it's the right tool: to capture a consistent voice or format, to improve accuracy on specialized tasks, to reduce cost by getting a smaller model to perform like a larger one, or to encode domain behavior that prompting can't reliably achieve. We handle the data preparation that makes or breaks the result, run rigorous before-and-after evaluation so improvement is measured rather than assumed, and build the pipeline to retrain and version the model as your needs evolve. And if fine-tuning isn't the answer, we'll tell you and point you to what is.

PipelineAI

From input to outcome

What an AI engagement actually moves through, stage by stage, and what has to be true at each boundary before the next stage can run.

Source data

Documents, events and system records are collected, cleaned and labelled.

In
Your systems
Out
Prepared corpus

Model & retrieval

Models are tuned and grounded in that corpus so answers trace to a source.

In
Prepared corpus
Out
Grounded output

Evaluation & guardrails

Automated evals, safety checks and human review where stakes demand it.

In
Grounded output
Out
Verified output

Production system

Served behind an API with monitoring, cost ceilings and a rollback path.

In
Verified output
Out
Decisions in product

Feedback edge

Production outcomes re-enter the evaluation set and the next round of tuning.

Selected Work

Proof, in production

Real systems, shipped and running: the interface, the data model, and the workflows they replaced.

AI Quality Assurance · Contact Centres

An AI scorecard for every conversation, with the reasons behind the grade

Voxalytics grades each call on a 100 point rubric and explains the grade in plain language: what the agent did well, where the call lost momentum, and what the buyer signals say about intent and churn risk. Supervisors send the scorecard to the agent or flag it for review from the same screen.

  • Plain-language summary of why the call scored the way it did
  • Score breakdown per stage with the exact points lost
  • Buyer intent, churn risk and lead grade next to the QA score
app.voxalytics.com/calls/qa-review
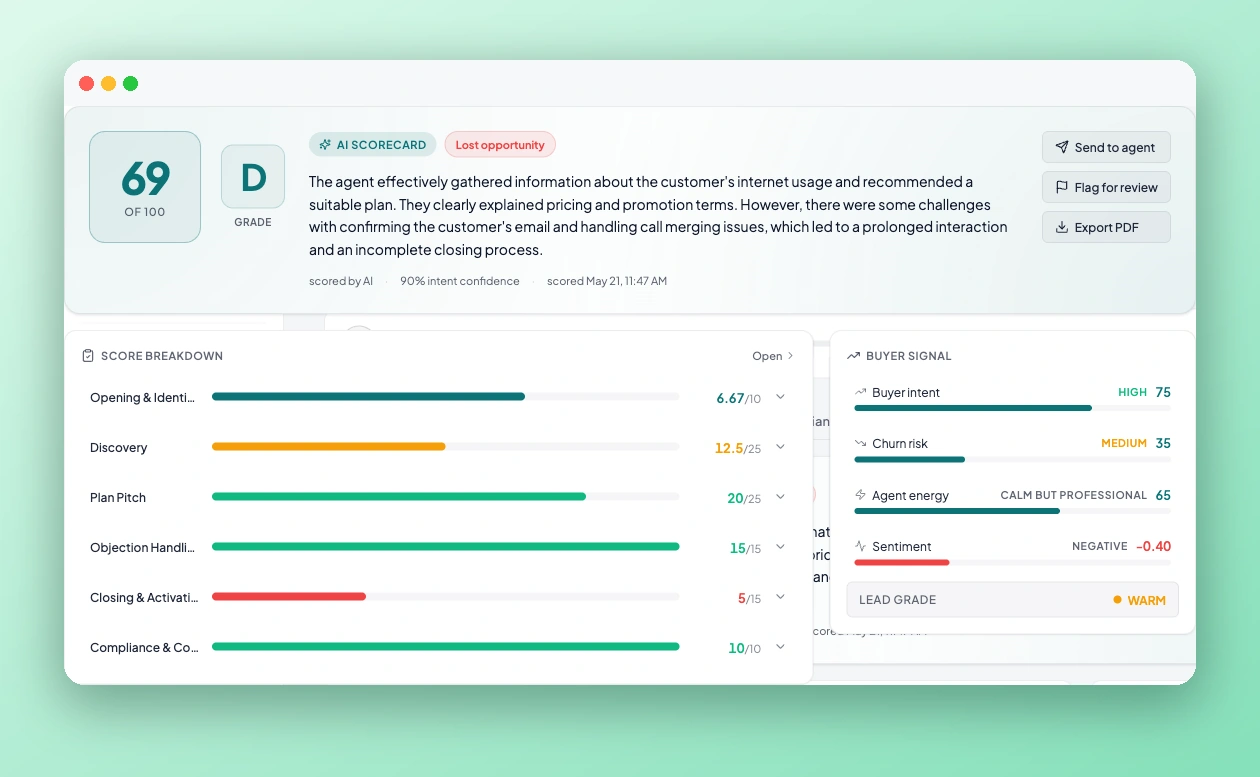
Voxalytics AI scorecard for a lost-opportunity call
AI Document Intelligence · Insurance

We cut underwriting review by 89% and made it audit-ready

A Series B insurance platform was capped by how fast underwriters could read unstructured documents to pull a handful of decision-critical fields. We built a document-intelligence pipeline with OCR, a fine-tuned extraction model, and a RAG layer that grounds every field in its source passage. A human-in-the-loop review UI lets underwriters confirm in seconds.

  • Fine-tuned extraction grounded to source passages for full auditability
  • Confidence scoring that routes only genuine edge cases to a human
  • Every decision logged to continuously improve the model
aptiva.app/submissions/SUB-40912
ASubmissionsSUB-40912liability_cert.pdf
Page 2 / 764%

Northbridge Mutual

Certificate of Liability Insurance

FORM CG-2010
REV 09/2025

Policy number

NBM-PL-4471-88A1

Named insured

Delgado Fabrication LLC2

Effective / expiry

01 Mar 2026 to 28 Feb 2027

Annual premium

$12,480.00 USD3

This certificate is issued as a matter of information only and confers no rights upon the certificate holder. It does not affirmatively or negatively amend, extend or alter the coverage afforded by the policies listed herein.

Should any of the above described policies be cancelled before the stated expiration date, the issuing insurer will endeavour to mail thirty (30) days written notice to the certificate holder named to the left, but failure to do so shall impose no obligation or liability of any kind upon the insurer, its agents or its representatives.

Authorized representative

Date

Coverage afforded by the policies described herein is subject to all the terms, exclusions and conditions of such policies. Limits shown may have been reduced by paid claims.

Extraction5 fields · 1 flagged
1Policy number

NBM-PL-4471-88A

99.4%page 2
2Named insured

Delgado Fabrication LLC

98.1%page 2
3Annual premium

$12,480.00

97.6%page 2
4Effective date

01 Mar 2026

99.0%page 2
5Risk tierReview

B · Standard

86.2%page 5

What we build and deliver

The fine-tuning work done right.

Dataset Engineering

Building, cleaning, and curating the training data that determines the outcome.

Fine-Tuning & Adaptation

Full and parameter-efficient (LoRA) tuning for accuracy, voice, and behavior.

Evaluation & Regression Harness

Before-and-after measurement that proves the tuned model is genuinely better, with guards that catch any degradation in safety or other behavior.

Smaller-Model Strategy

Tuning compact models to match larger ones, cutting inference cost.

Retraining Pipelines

Versioned pipelines to retrain and update the model as your needs evolve.

Use cases

Where it creates value

Where fine-tuning genuinely earns its place.

Brand & Content

Consistent voice

A model that writes in your specific voice. It holds your format too, reliably.

Specialized Domains

Domain accuracy

Niche tasks that generic models handle poorly. Tuning lifts performance on the work specific to your domain.

High Volume

Cost reduction

A smaller tuned model that matches a larger one at a fraction of the cost.

Structured Output

Reliable formats

Consistent structured outputs where prompting alone is flaky.

Classification

Custom classifiers

Tuned models for specialized classification work.

Extraction

Extraction tasks

Tuned models for specialized extraction tasks.

Privacy-sensitive

Open-model tuning

Open models, fine-tuned to your tasks. You deploy them on your own infrastructure. Control and privacy stay with you.

Business outcomes

The return on the work

What the right fine-tuning returns.

Yours
A model that fitsBehavior, voice, and format tuned to exactly what you need, performing better and more reliably on your specific tasks.
40%
Lower inference costSmaller tuned models that perform like larger, pricier ones.
Proven
By evaluationImprovement measured rigorously before anyone claims it.
FAQ

Questions we get before we start

Still unresolved? A 30-minute conversation with an engineer usually settles it faster than another page of copy.

Often not, and we'll tell you honestly. Prompting and retrieval (RAG) solve many problems faster and cheaper. Fine-tuning is the right tool for consistent voice or format, specialized-task accuracy, cost reduction via smaller models, and behavior prompting can't reliably achieve. We assess your actual need before recommending it.

RAG feeds a model relevant information at query time without changing the model; it's best for factual accuracy and currency. Fine-tuning changes the model's weights to alter its behavior; it's best for voice, format, specialized tasks, and cost. They solve different problems and are sometimes combined.

Less than people expect for many tasks: sometimes a few hundred high-quality examples. Quality matters far more than quantity; a small, clean, well-curated dataset beats a large messy one. We assess what you have and what's needed during scoping.

Often, yes. A fine-tuned smaller model can match a larger, more expensive one on your specific tasks, cutting inference cost significantly at scale. We measure this explicitly so the savings are real.

We build an evaluation harness and measure performance before and after tuning on your real tasks. Improvement is proven by data, not assumed. We also check that tuning didn't degrade safety or other behavior.

Yes. We fine-tune open-weight models you can deploy on your own infrastructure, giving you full control and privacy. That matters for regulated or sensitive use cases.

Yes. We build versioned retraining pipelines so the model can be updated as your data and needs evolve, rather than being a one-time artifact that drifts out of date.

Now taking new projects

Tune a model that fits.

Tell us where generic models fall short. We'll tell you honestly if fine-tuning is the answer, and do it right if it is.