Data Engineering

Turn scattered data into decisions you can trust

Great analytics and reliable AI both rest on the same foundation: clean, unified, trustworthy data. We build the pipelines, warehouses, and real-time infrastructure that turn your scattered data into a single source of truth.

OverviewCloud & Data · Data Engineering

Every good decision and every good model starts with good data

Data is the asset every company has and few truly use. It accumulates in CRMs, product databases, spreadsheets, SaaS tools, and event streams. Most of the time it sits there, fragmented and contradictory, while teams make decisions on gut feel and stale reports. The companies that pull ahead are the ones that turn that raw material into a reliable, unified foundation: a single source of truth that powers analytics, reporting, and increasingly, AI. Building that foundation is the work of data engineering.

Data engineering is the discipline of designing and building the systems that collect, move, store, transform, and serve data at scale. It spans the pipelines that pull data from every source, the warehouses and lakes where it's stored and modeled, the transformations that make it clean and consistent, the real-time streams that power live experiences, and the governance that keeps it trustworthy and compliant. It's unglamorous, foundational work, and it's the difference between analytics you can bet the business on and dashboards no one quite believes.

The need has intensified sharply with AI. A machine learning model is only as good as the data feeding it, and the single most common reason AI projects stall is data that isn't ready: fragmented, unlabeled, low-quality, or impossible to access reliably. Before AI can deliver, the data foundation has to be solid. The same foundation that makes AI possible also transforms everyday decision-making, turning week-old manual reports into real-time, trustworthy dashboards that the whole organization can act on.

Villaex builds that foundation with the same engineering discipline we bring to everything else. We design pipelines that are reliable and observable, warehouses modeled for the questions you actually ask, transformations that are tested and documented, and governance that keeps data accurate, lineage-traceable, and compliant. The outcome is a data platform you can trust, one that powers better decisions today and makes the AI you'll want tomorrow actually possible.

PipelineCloud & Data

From input to outcome

How scattered systems become one governed source of truth, and what each layer guarantees to the layer above it.

Sources

Databases, APIs, SaaS tools and event streams, connected once and documented.

In
Every system
Out
Raw extracts

Pipelines

Automated ingestion with retries, alerting and freshness monitoring.

In
Raw extracts
Out
Landed data

Warehouse & models

Tested, version-controlled transformations into governed, documented tables.

In
Landed data
Out
Trusted tables

Analytics & AI

Dashboards, self-serve analytics and the feature sets models train on.

In
Trusted tables
Out
Decisions & models

Feedback edge

Quality tests and lineage checks report failures back to the pipeline layer.

Where this work usually breaks down

The data problems holding companies back are remarkably consistent.

Data trapped in silos

Information scattered across tools that don't talk, so no one has the whole picture and every report requires manual stitching.

Numbers no one trusts

Reports that disagree depending on who runs them, eroding confidence and slowing every decision.

Manual, brittle reporting

Analysts spending days copying data between spreadsheets to produce reports that are stale the moment they're done.

Data that isn't AI-ready

Fragmented, unlabeled, low-quality data that quietly kills machine learning initiatives before they start.

No governance or lineage

No way to trace where a number came from, no quality checks, and growing privacy and compliance exposure.

Can't scale or go real-time

Pipelines that break under volume or can't deliver the live data modern products and decisions require.

Our approach

We build the data foundation deliberately, for reliability and trust.

Unified pipelines

Reliable, automated flows that pull from every source into one place. No more manual stitching.

Modeled warehouses

Warehouses designed around the questions you actually ask, so analytics are fast and answers are consistent.

Tested transformations

Clean, documented, version-controlled transformations (dbt and friends) that make data trustworthy.

Real-time streaming

Streaming infrastructure for the live data that modern products and decisions increasingly require.

Governance & quality

Lineage, automated quality checks, access control, and privacy handling built into the platform.

Analytics & BI

Dashboards and self-serve analytics that put trustworthy, current data in front of the people who need it.

Selected Work

Proof, in production

Real systems, shipped and running: the interface, the data model, and the workflows they replaced.

Unified Data Platform · Retail

From conflicting reports to one source of truth

Sales, inventory, and customer data lived in systems that never agreed, and a planned AI project was blocked because the data wasn't usable. We built a unified platform with automated pipelines into a modeled warehouse, tested transformations, real-time dashboards, and governance. It became the foundation for everything next.

  • Automated pipelines from every system into one warehouse
  • Tested, version-controlled transformations and lineage
  • Real-time dashboards the whole org could trust
quantvue.io/explore/revenue-by-region
ExploresRevenue by region

Net revenue by region

Weekly · USD · 12 Dec 2025 to 12 Mar 2026

WestMidwestNortheast
$120k$90k$60k$30k$0
W10 · West $118.4k
Dec 15Jan 05Jan 26Feb 16Mar 09
RegionOrdersNet revenueΔ prior
West18,402$1,284,910+12.4%
Midwest12,865$842,377+6.1%
Northeast9,143$611,204−2.8%
South7,690$498,552+3.7%
Mountain5,218$342,088+1.2%
Demand Forecasting · Food Production

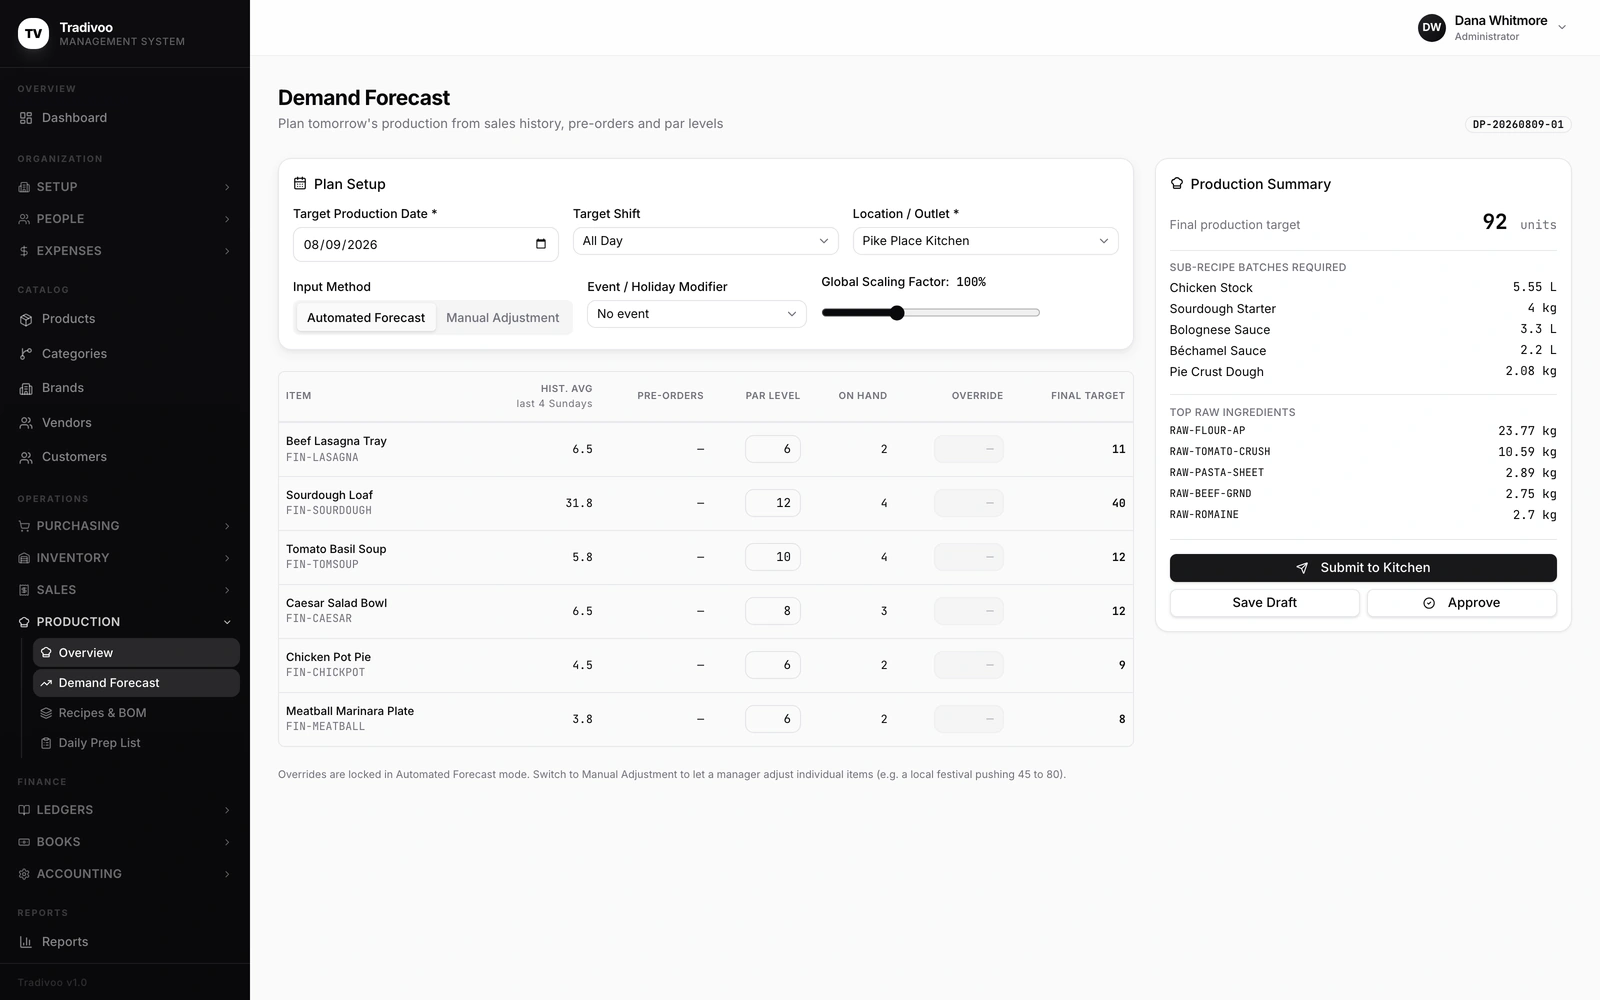
Tomorrow's production planned from sales history and par levels

Tradivoo's demand forecast plans the next production run for a kitchen or plant from the last four weeks of sales, pre-orders, par levels and stock on hand. It rolls the finished goods into sub-recipe batches and raw ingredient quantities, so the kitchen gets a prep list, not a spreadsheet.

  • Forecast per item from history, pre-orders and par levels
  • Sub-recipe batches and raw ingredients computed automatically
  • Event modifiers and manual overrides with approval
app.tradivoo.com/production/forecast
Tradivoo demand forecast planning tomorrow's production

What we build and deliver

The complete data stack, engineered for trust.

Data Pipelines

Automated ingestion and ETL/ELT from every source: databases, APIs, SaaS tools, and event streams.

Data Warehouses

Cloud warehouses and lakes modeled for performance and the questions your business actually asks.

Real-Time Streaming

Streaming infrastructure for live dashboards, real-time features, and event-driven systems.

Data Transformation

Tested, documented transformations that turn raw data into clean, consistent, analysis-ready tables.

Analytics & BI

Dashboards and self-serve tools that make trustworthy data accessible across the organization.

Quality & Lineage

Automated quality monitoring and lineage that runs end to end, so any number on a dashboard can be traced back to its source.

Access & Privacy

Access control and privacy handling, so the right people see the right data and the platform stays compliant.

Use cases

Where it creates value

A solid data foundation changes what's possible across the business.

Leadership & Operations

Single source of truth

Conflicting reports give way to unified, real-time dashboards everyone trusts. Leadership and the teams running the business day to day read the same numbers, in the place the work happens.

AI initiatives

ML-ready data

The clean, accessible, governed data foundation that makes machine learning projects succeed.

Product

Product analytics

Event pipelines feed analytics that reveal how users actually behave. Product decisions get made against what they do.

Finance

Automated reporting

Reporting runs end to end on its own. Reconciliation goes with it. What used to take days of manual spreadsheet work no longer takes anyone's day.

Marketing

Unified customer data

Customer data integrated across channels for accurate attribution and segmentation.

Business outcomes

The return on the work

What a trustworthy data foundation returns.

1
Current source of truthConflicting reports replaced by unified numbers the whole organization trusts, current at the moment a decision gets made instead of a week behind it.
90%
Less manual reportingAnalysts freed from spreadsheet drudgery to do real analysis.
Ready
For AIThe foundation that turns stalled machine learning ambitions into shipped systems.
How we deliver

How the work actually runs

From audit to live platform, built for trust at every step.

  1. Discovery

    We start by understanding the business, not the brief. Workshops with your team map goals, constraints, data, and the metrics success will be measured against, before anyone writes a line of code.

  2. Planning & Architecture

    We translate the problem into a system: data flows, model choices, interfaces, integrations, and a delivery plan broken into milestones you can evaluate at each step.

  3. Design

    Experience and technical design happen together. We prototype the critical flows early so stakeholders can react to something real instead of a slide deck.

  4. Development

    Senior engineers build in tight, two-week iterations. Every increment is reviewed, tested, and demoed, so progress is visible and course-corrections are cheap.

  5. Testing & QA

    Automated tests, security reviews, performance profiling, and human QA run continuously, not as an afterthought. We ship when it's genuinely ready.

  6. Deployment

    We harden infrastructure, set up CI/CD, observability, and rollback safety, then ship to production with a launch plan that protects uptime and data.

  7. Support & Scale

    After launch we monitor, optimize, and evolve. As usage grows, the architecture grows with it, and the same team that built it keeps it healthy.

The stack we build on

Warehouses & Lakes

SnowflakeBigQueryRedshiftDatabricksPostgreSQL

Pipelines & Transform

AirflowdbtFivetranDagster

Streaming

KafkaKinesisFlink

BI & Analytics

LookerMetabasePower BITableau

Industry coverage

SaaSFinanceRetailHealthcareLogisticsManufacturingMedia
FAQ

Questions we get before we start

Still unresolved? A 30-minute conversation with an engineer usually settles it faster than another page of copy.

Data engineering builds the infrastructure: the pipelines, warehouses, and platforms that collect, store, and serve data reliably. Data science analyzes that data to produce insights and models. Engineering is the foundation; science is built on top of it. Most failed analytics and AI projects fail at the engineering layer, which is why we focus there.

If you're combining data from multiple sources for analytics or AI, almost certainly yes. A warehouse gives you one place where data is unified, modeled, and fast to query. That is the foundation for trustworthy reporting. We'll recommend the right platform and design for your scale and budget.

Yes. It's one of the most common problems we solve. Conflicting reports come from data living in silos and being transformed inconsistently. We unify the data, define transformations once in a tested, version-controlled way, and create a single source of truth everyone works from.

You start exactly there, with the data. We assess your data readiness honestly, then build the pipelines, quality, and governance that make AI possible. It's unglamorous but essential; skipping it is the single most common reason AI projects fail.

Yes. We build streaming infrastructure for live dashboards, real-time product features, and event-driven systems, using the right tools for your latency and volume requirements.

Through automated quality checks, tested transformations, monitoring and alerting on pipelines, and data lineage so every number is traceable to its source. Quality is engineered in, not inspected at the end.

Governance is part of the platform: access controls, PII handling, audit logging, and lineage that support GDPR, CCPA, HIPAA, and other requirements depending on your industry.

Yes. We build with accessible tools, document thoroughly, and run knowledge transfer so your analysts and engineers can self-serve and extend the platform independently.

Now taking new projects

Build a foundation you can trust.

Tell us where your data hurts. We'll turn the mess into a single source of truth, and the foundation for what's next.